Getting it into your agent
It runs from inside its repository, so the clone comes first — what it calls does not travel with the file alone.
git clone --depth 1 https://github.com/ASI2030/Fact-Check-Xnpx agentmods add skills/asi2030/fact-check-x/fact-check-x-completeWrote this? Show the measurements
A badge with what this costs and how it scanned, read live from this page, so it follows the numbers instead of freezing them. Markdown for a README, HTML for a documentation site or a project page.

[](https://agentmods.dev/skills/asi2030/fact-check-x/fact-check-x-complete)<a href="https://agentmods.dev/skills/asi2030/fact-check-x/fact-check-x-complete"><img src="https://agentmods.dev/badge/skills/asi2030/fact-check-x/fact-check-x-complete/github.svg" alt="Measured on agentmods" height="20"></a>Or the 80×15 button, for a site that already has a row of RSS and ATOM ones. Only the verdict fits; the numbers stay here.

<a href="https://agentmods.dev/skills/asi2030/fact-check-x/fact-check-x-complete"><img src="https://agentmods.dev/badge/skills/asi2030/fact-check-x/fact-check-x-complete.svg" alt="Reviewed on agentmods" width="80" height="20"></a>What it costs to keep this loaded
Counted locally with the o200k_base tokenizer, which is exact for GPT models; Claude uses its own tokenizer and its counts differ. Treat this as one consistent yardstick across the catalogue rather than a bill. Prices are per million input tokens.
| Model | Per session | Once invoked |
|---|---|---|
| Fable 5.1 | $0.00180 | $0.10829 |
| Opus 5.5 | $0.00072 | $0.04332 |
| Sonnet 5.5 | $0.00036 | $0.02166 |
| Haiku 4.5 | $0.00018 | $0.01083 |
Grade A, and why
fact-check-x-complete scanned grade A with 0 findings against 26 rules in 11 categories — prompt injection, anti-refusal, data exfiltration, privilege escalation, supply chain, agent snooping, system-prompt leakage, SSRF and excessive agency — measured 8d ago.
A static scan of the body, not an audit. Every finding is printed with the line that produced it so you can judge whether it matters here. A mod is markdown that instructs an agent; that is exactly why what it instructs is worth reading.
Nothing flagged
None of the 26 patterns this scan looks for appear in this file: no shell pipes, no recursive deletes, no credential paths, no hidden text, no instruction-override or anti-refusal phrasing, no agent-config snooping. That is not a guarantee, it is the absence of the things that are checkable.
How it starts
The opening of the file, as written. The whole thing — 393 lines — stays where its author put it; the contents beside it link to each section on GitHub.
全知晓(Fact-Check-X)
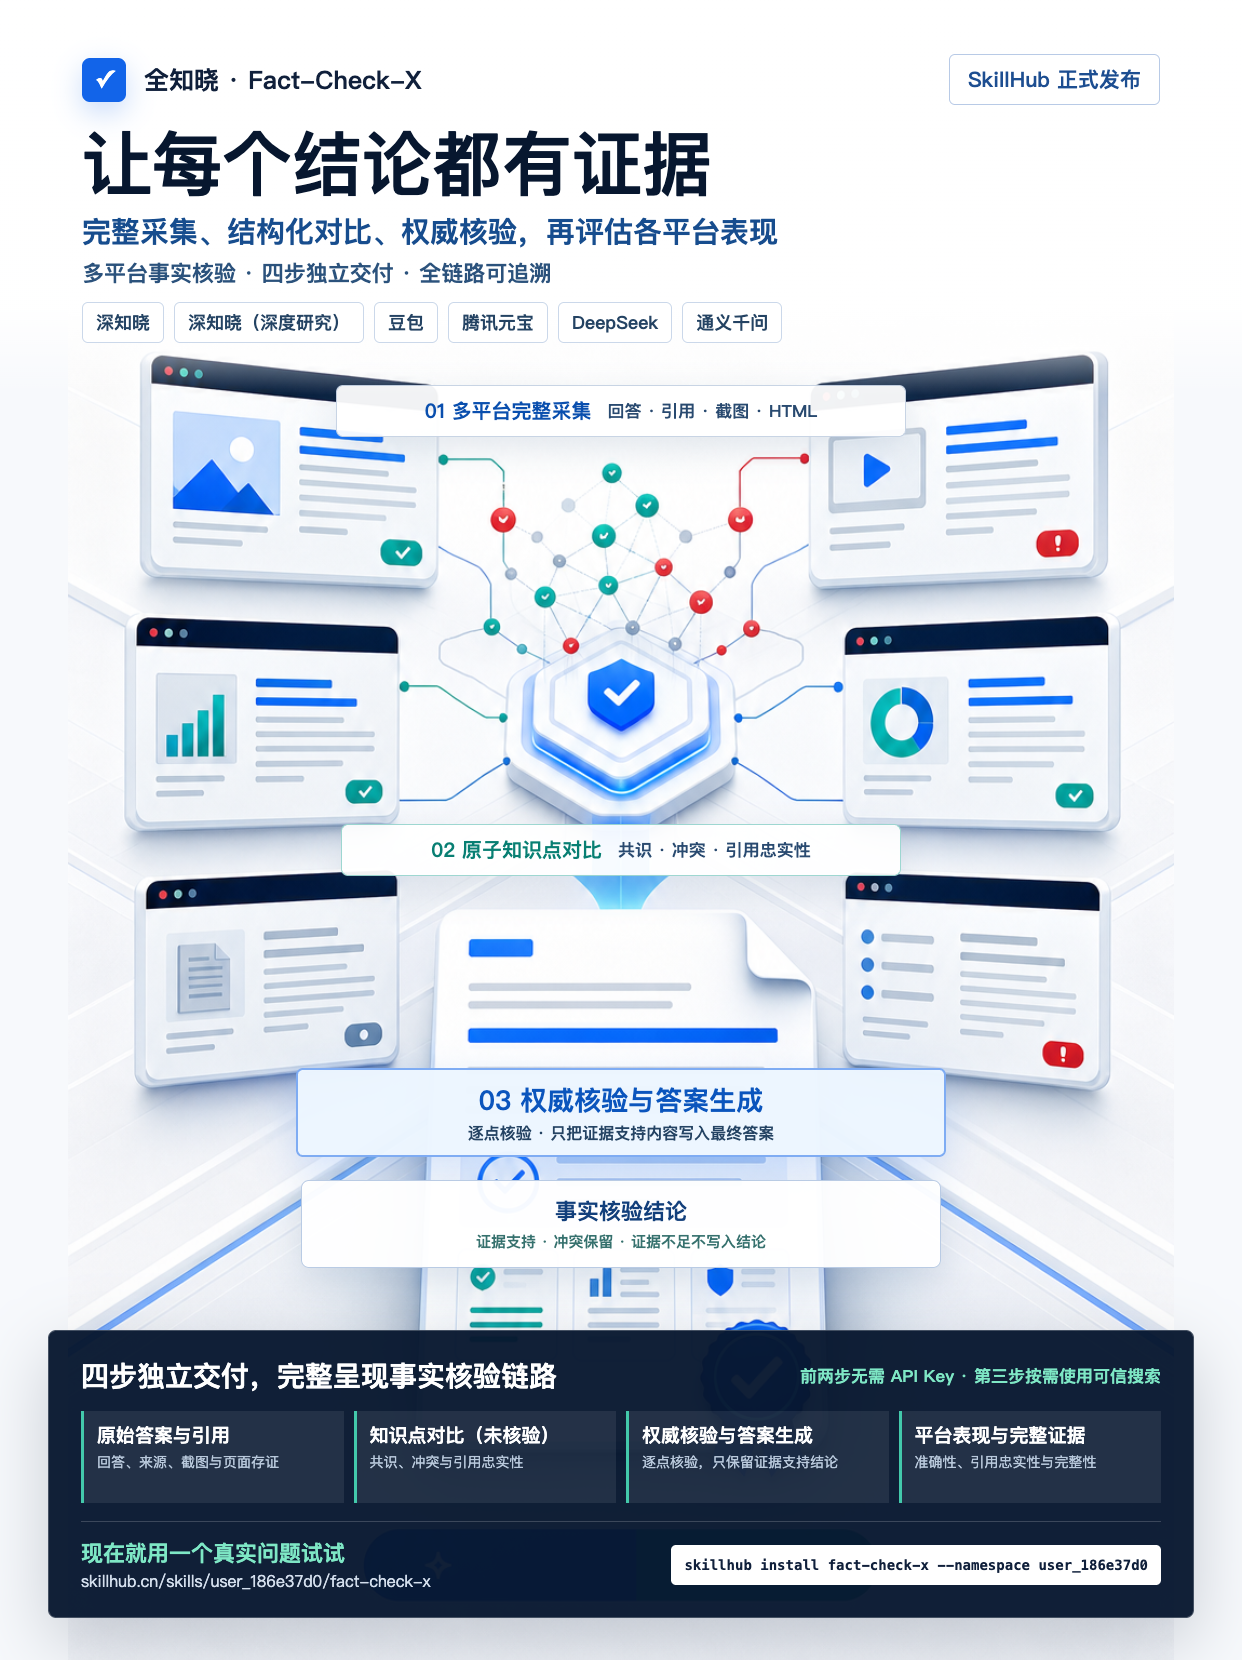
把同一个问题交给一个或多个 AI 平台,完整保留每家的回答和引用,再把关键事实逐点对齐、核验并评估各平台表现。第三步会基于权威证据生成最终答案,但不会用“答案生成”代替完整事实核验:证据冲突会被保留,官方无法查证的内容统一标为“疑似误导”,移入补充参考风险区且不写入确定结论。用户只需说出问题和要比较的平台,不需要学习平台 ID、内部流程编号或报告术语。
支持平台
当前内置以下网页端平台,按用户本次输入动态选择任意 N≥1 个:
| 平台 | 能力 |
|---|---|
| 深知晓 | 标准问答、引用与官方来源采集 |
| 深知晓(深度溯源) | 等待普通回答完成后在同一会话启动深度溯源,并作为独立结果采集 |
| 豆包 | 回答、引用与页面存证 |
| DeepSeek | 回答、引用、逐条来源正文与页面存证 |
| 通义千问 | 回答、引用、逐条来源正文与页面存证 |
| 腾讯元宝 | 回答、引用、逐条来源正文与页面存证 |
平台由用户选择,不存在固定“五平台模式”。N=1 可完成单平台事实核验;N≥2 会额外比较各平台的共识、冲突和来源差异。网页结构变化时,技能会明确报告失败并停在当前阶段,不会用部分结果冒充完整报告。 |
使用体验
- 用户只需提供核验问题和想比较的平台;没有指定平台时,立即列出“深知晓、深知晓(深度溯源)、豆包、DeepSeek、通义千问、腾讯元宝”供用户选择,不得漏掉深度溯源,也不要求用户记平台 ID。
- 第一次使用某个平台时打开浏览器,由用户本人完成登录或验证码;会话保存后自动复用。
- 每一步都交付可打开的独立报告:各方答案汇总、各方答案聚合(未核验)、权威核验后的最终答案、各方答案测评报告。
- 每份阶段报告展示后都必须等待用户明确选择继续、修正或结束;最初要求完整执行不能替代逐阶段确认。
- 第二步在概览和逐知识点明细中分别展示直接答案与补充参考;第三步只保留权威最终答案;第四步以一个锁定明细区承接第三步结果并分区测评。
- 第三步只展示最终答案、权威证据和证据边界;第四步只消费已锁定的第三步数据,负责平台裁决、指标与表现对比,不重算第三步。
- 第四步覆盖率只衡量“答没答到”:答到即算覆盖,证据是否充分由证据充分率单独体现。仅当一个知识点在所有平台中都是未回答或证据不足时,才整体移出覆盖率与准确率分母。
- “编造式幻觉”和“证据不足”只作为内部原始裁决状态保留;对用户统一显示为“疑似误导”,移入补充参考风险区并在报告上方突出。每个知识点的长依据默认收起,点击后可看完整原文。
- 来源采集、可信搜索等技术动作失败时原则上停止;若流程仍继续,每一步报告都必须在显著位置提示技术失败及影响,相关主张继续按“疑似误导”呈现。
- 原答案的引用存在性与来源支持性独立保留。
attachedReferenceIndexes为当前摘录观察到的引用,citedReferenceIndexes为校验采用的证据;抓取失败或不支持不能写成“平台未附依据”。跨句、跨表格行的引用必须回到对应主张检查,不得借用邻行脚标。 - 拆解主张时保留年度、政策项目、适用对象与条件。历史公示不能省略年度改写为现行政策;不同项目的金额不得直接当作同一事实冲突。金额必须与单位匹配,年份、备案号不能充当金额证据。
- 多平台采集与知识点对比不需要 API Key。只有用户继续进行权威证据核验,且现有材料不足以直接裁决时,才检查可信搜索配置。
- 可信搜索未配置时,只引导用户登录深知智能平台;技能自动获取或创建专用 Key 并安全保存在本机,不要求用户复制粘贴密钥。
- 语义分析由 Codex、Claude Code、WorkBuddy 等当前运行载体完成,不调用外部大模型 API。
强制执行门禁(任何动作前先读)
- 语言硬门禁:读取本技能后的第一句话、过程更新、命令说明、阶段检查点、错误说明和最终答复全部只使用简体中文;不得输出英文句子。命令、路径、平台 ID 和数据字段名可以保留原文。第一条回复直接使用“我会核验这个问题:先采集您选择的平台原回答和引用,再比较共识与分歧;如需权威结论,最后用可信搜索逐点核验。每一步都会给您一份可打开的报告。”,不得先用英文介绍技能或内部流程编号。
- 执行任何命令前先检查当前会话可调用的工具。完整在线采集优先由包内 Playwright 直接启动并控制系统 Chrome、Microsoft Edge、Brave 或 Chromium;Computer Use 不是正常采集的前置条件。页面结构变化时先运行选择器恢复与验证层;当前载体自带的浏览器或 Computer Use 是首选诊断手段,
agent-browser只可作为失败后的可选诊断工具,不是依赖,也不得直接交付答案或改写适配器。只有命令工具时可以前台执行一次login验证可见浏览器,但没有真实成功输出前不得声称浏览器已启动。 - 所有流水线命令必须前台直接执行并等待真实退出状态,包括
login、run、prepare-comparison、complete-comparison、prepare-authority、search-authority、finalize-authority、reopen-authority和deliver。执行工具因等待用户操作而返回可轮询的运行会话 ID 时,应保留并轮询该会话;禁止使用 shell 后台任务,禁止给任何流水线命令添加| tail、| tee、|| true或其他会掩盖退出码的包装。 login是可见浏览器命令,必须严格按本技能给出的参数执行,不得添加--headed或其他未列出的参数。精确命令尚未失败时,不得先检查 CLI 帮助、源码或浏览器环境;精确命令失败后只按错误与capture-recovery.json恢复。- 未看到
login成功、可提问页面已建立或results.json全平台成功证据前,禁止告诉用户“浏览器已启动”“采集已在后台运行”或“将自动进入后续流程”。 login或run运行期间出现登录、短信验证码、人机验证或 CAPTCHA 时,保持命令和当前 Playwright 页面运行,立即提示用户本人处理;检测到处理完成后自动继续,不得关闭页面、重输问题或提前结束任务。login或run非零退出、浏览器意外关闭、人工处理超时或采集失败时,立即读取capture-recovery.json,主动调用宿主浏览器工具或 Computer Use 恢复。两者都不可用时才说明能力缺失并停在原始答案采集阶段。- 进入恢复后,禁止改用 headless/无头浏览器、清理锁文件或修改启动参数规避接管。先读取
captureLifecycle:只要submissionAttempted、submissionConfirmed或answerObserved为真,就禁止重新填入、提交或询问同一问题,只能恢复原会话并继续等待、定位或提取现有回答。只有resubmissionAllowed=true时才可提交一次。选择器候选必须经过程序的唯一、可见、可编辑或非进度文本门禁;模型、Computer Use 和agent-browser都只能提议,不能直接采用或写回适配器。 capture-gate.json未证明所有指定平台均成功前,禁止进入知识点对比和后续流程。不得用已有材料、搜索结果、空回答或部分成功结果替代失败平台。- 分阶段交付门禁:原始答案采集、知识点对比和权威证据核验各自完成后,必须先向用户发送本阶段真实可打开的独立产物,再询问用户选择“继续下一步”“修正当前结果”或“到此结束并保留产物”。程序会在
stage-checkpoints.json记录产物摘要和一次性确认令牌;收到用户“继续下一步”后,必须用acknowledge-stage --decision continue提交该令牌,否则下一阶段命令会直接失败。即使用户最初要求完整连续执行,也不能跳过阶段产物展示和用户确认。内部证据不足状态属于可交付边界,面向用户统一显示为“疑似误导”,不阻断后续报告。
What ships with it
60 files beside SKILL.md in the same directory: the scripts, references and assets a skill reads on demand. Not counted in the per-session cost; read them before you install if any of them is executable.
- agents/openai.yaml 355 B
- LICENSE 11 KB
- modules/fact-check-x-authoritative-verify/references/acceptance-criteria.md 2.3 KB
- modules/fact-check-x-authoritative-verify/references/contracts.md 4.5 KB
- modules/fact-check-x-authoritative-verify/references/final-report-baseline.html 106 KB
- modules/fact-check-x-authoritative-verify/scripts/authority_verify.py 39 KB runs code
- modules/fact-check-x-authoritative-verify/scripts/batch_search.py 5.6 KB runs code
- modules/fact-check-x-authoritative-verify/scripts/common.py 967 B runs code
- modules/fact-check-x-authoritative-verify/scripts/platform/participants.json 869 B
- modules/fact-check-x-authoritative-verify/scripts/policy_match.py 2.9 KB runs code
- modules/fact-check-x-authoritative-verify/scripts/render_authority_report.py 25 KB runs code
- modules/fact-check-x-authoritative-verify/scripts/render_final_report.py 24 KB runs code
- modules/fact-check-x-authoritative-verify/scripts/render_platform_report.py 55 KB runs code
- modules/fact-check-x-authoritative-verify/SKILL.md 7.3 KB
- modules/fact-check-x-authoritative-verify/tests/anchor_conflict_test.py 1.5 KB runs code
- modules/fact-check-x-authoritative-verify/tests/dknow_authority_contract_test.py 969 B runs code
- modules/fact-check-x-authoritative-verify/tests/fixtures/K1-assessment.json 335 B
- modules/fact-check-x-authoritative-verify/tests/fixtures/K1-request.json 1.5 KB
- modules/fact-check-x-authoritative-verify/tests/fixtures/K2-assessment.json 370 B
- modules/fact-check-x-authoritative-verify/tests/fixtures/K2-evidence-fixture.json 173 B
- modules/fact-check-x-authoritative-verify/tests/fixtures/K2-request.json 903 B
- modules/fact-check-x-authoritative-verify/tests/geography_test.py 3.0 KB runs code
- modules/fact-check-x-authoritative-verify/tests/metrics_denominator_test.py 3.5 KB runs code
- modules/fact-check-x-authoritative-verify/tests/model_judgment_test.py 2.4 KB runs code
- modules/fact-check-x-authoritative-verify/tests/policy_equivalence_test.py 4.1 KB runs code
- modules/fact-check-x-authoritative-verify/tests/smoke_test.py 54 KB runs code
- modules/fact-check-x-knowledge-compare/references/acceptance-criteria.md 2.8 KB
- modules/fact-check-x-knowledge-compare/references/contracts.md 4.9 KB
- modules/fact-check-x-knowledge-compare/scripts/common.py 967 B runs code
- modules/fact-check-x-knowledge-compare/scripts/knowledge_compare.py 61 KB runs code
- modules/fact-check-x-knowledge-compare/scripts/policy_match.py 2.9 KB runs code
- modules/fact-check-x-knowledge-compare/scripts/render_comparison.py 21 KB runs code
- modules/fact-check-x-knowledge-compare/SKILL.md 4.5 KB
- modules/fact-check-x-knowledge-compare/tests/citation_presence_test.py 180 B runs code
- modules/fact-check-x-knowledge-compare/tests/deepseek_reference_faithfulness_test.py 180 B runs code
- modules/fact-check-x-knowledge-compare/tests/fixtures/comparison-analysis.json 3.0 KB
- modules/fact-check-x-knowledge-compare/tests/fixtures/results.json 1.3 KB
- modules/fact-check-x-knowledge-compare/tests/model_judgment_test.py 3.6 KB runs code
- modules/fact-check-x-knowledge-compare/tests/requirements_scope_test.py 180 B runs code
- modules/fact-check-x-knowledge-compare/tests/smoke_test.py 76 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/auth-state.js 1.7 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/browser-session.js 5.6 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/generic-chat.js 153 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/login-recovery.js 1.6 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/platform-registry.js 8.8 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/providers/dknowc-chat.js 166 B runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/resume.js 5.9 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/capture/selector-recovery.js 8.6 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/cli.js 26 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/report-cli.js 2.8 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/report/html-report.js 44 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/report/markdown-report.js 5.5 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/report/reference-matrix.js 1.4 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/report/source-level.js 2.5 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/schema/result.js 4.4 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/trusted-search-onboarding.js 10 KB runs code
- modules/llm-answer-reference-compare/assets/tool/dist/utils/filesystem.js 578 B runs code
- modules/llm-answer-reference-compare/assets/tool/dist/utils/profile.js 341 B runs code
- modules/llm-answer-reference-compare/assets/tool/dist/utils/urls.js 1.1 KB runs code
- modules/llm-answer-reference-compare/assets/tool/LICENSE 1.1 KB
What this file has done since we first saw it
Hashed on every crawl. A supply-chain change to an agent config is a question of when, not whether, so the history is kept rather than the latest state alone.
- 8d ago Changed · +31 lines 517d5d065c8d
- 11d ago Changed · +12 lines e109d03a4974
- 1mo ago Changed · +12 lines 5a85f1d3bb1a
- 1mo ago Changed · +4 lines e24b97a931c1
- 1mo ago Changed · +1 lines 2f7bcf12c64e
- 1mo ago Changed · +3 lines e2e93e623a48
- 1mo ago Changed · +2 lines 9657e4395ab0
- 1mo ago Changed · +2 lines eafdeec40305
- 1mo ago First seen · 326 lines · 180 tokens per session scan A 24fc4122e003
fact-check-x-complete is a skill published in the GitHub repository ASI2030/Fact-Check-X (4 stars, last pushed 8d ago), licensed Apache-2.0. It adds 180 tokens to every session and 10,829 once invoked, about $0.0007 per session on Opus 5.5. A static security scan graded it A with 0 findings. No closer match exists in the catalogue, so it is treated as the original; first seen 2026-08-31.
Other skills, from other repositories
academic-writing
Scholarly writing and research compliance. Use for CRediT, preregistration, Plan S, Nelson Memo, preprints, ORCID, LLM disclosure.
accessibility-compliance
Web accessibility patterns for news and academic sites. Use for WCAG audits, alt text, accessible data viz, and assistive tech.
newsletter-publishing
Email newsletter workflows. Use when creating newsletters, building subscriber lists, designing templates, or tracking engagement.
photo-metadata
Embeds photo IPTC/EXIF/XMP metadata, caption, credit, alt text, license, AI-source label, GPS stripping, and C2PA credentials.
crisis-communications
Crisis communication and rapid-response workflows. Use when covering breaking news or coordinating fast fact-checking on deadline.
systematic-debugging
Use when encountering any bug, test failure, or unexpected behavior, before proposing fixes.